Secure Your AI-Enabled Applications Before They're Weaponised
Purpose-built penetration testing for LLM-powered apps, AI agents, RAG pipelines, and generative AI systems — uncovering novel attack surfaces that conventional tools miss entirely.
What is AI-Enabled Application Security Testing?
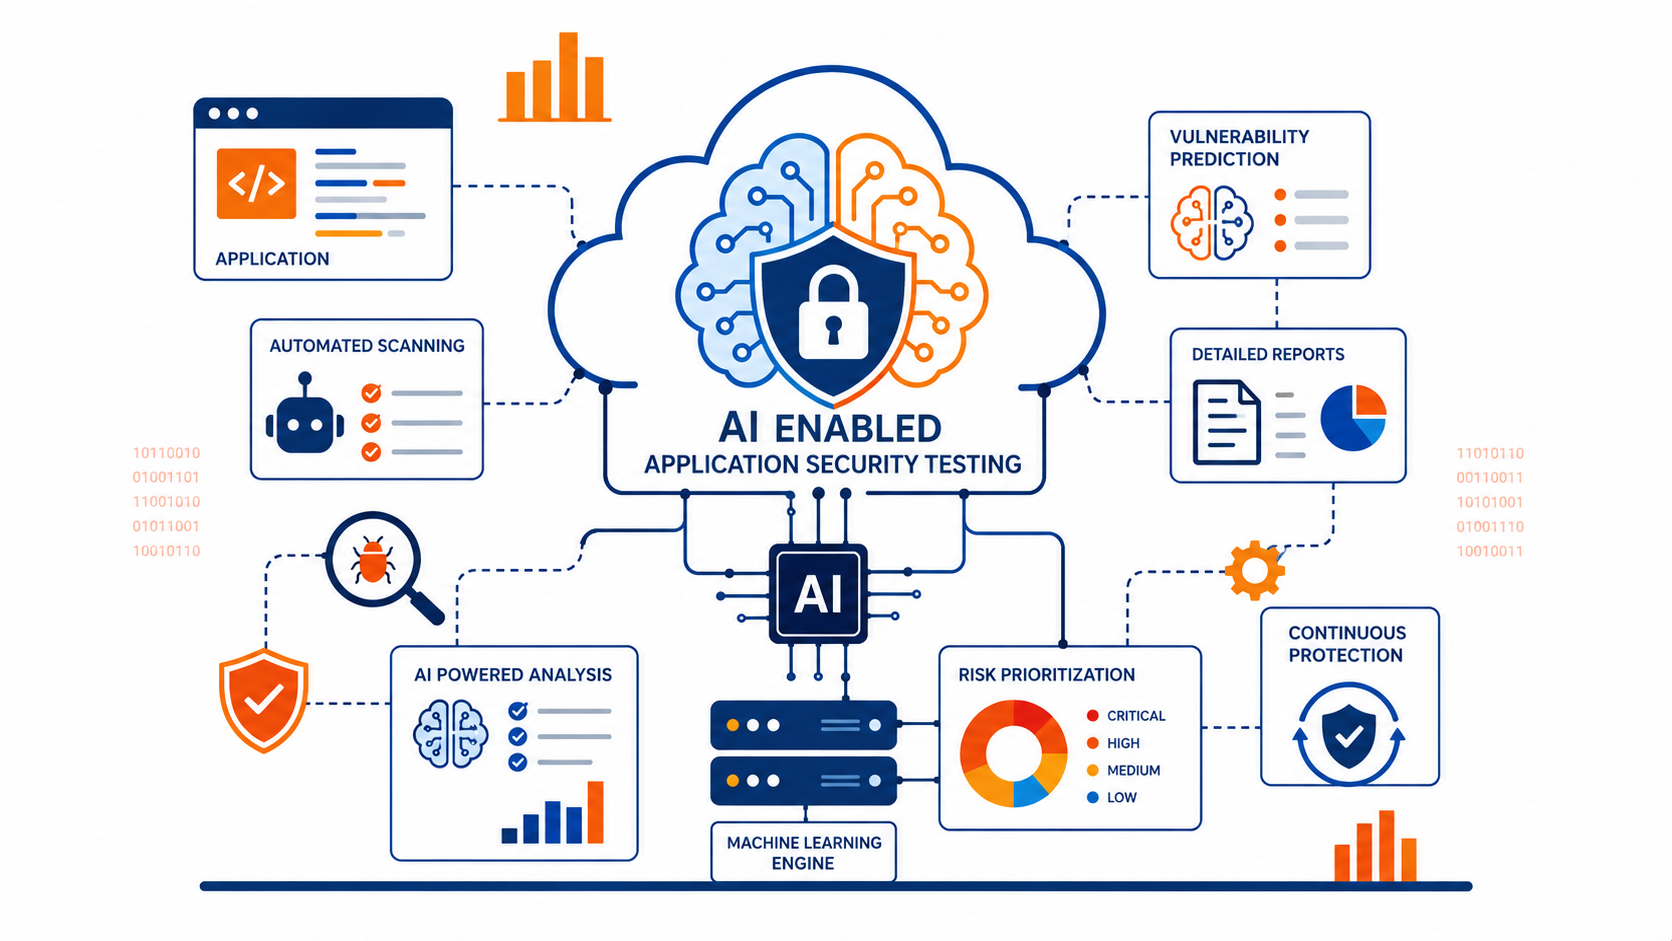
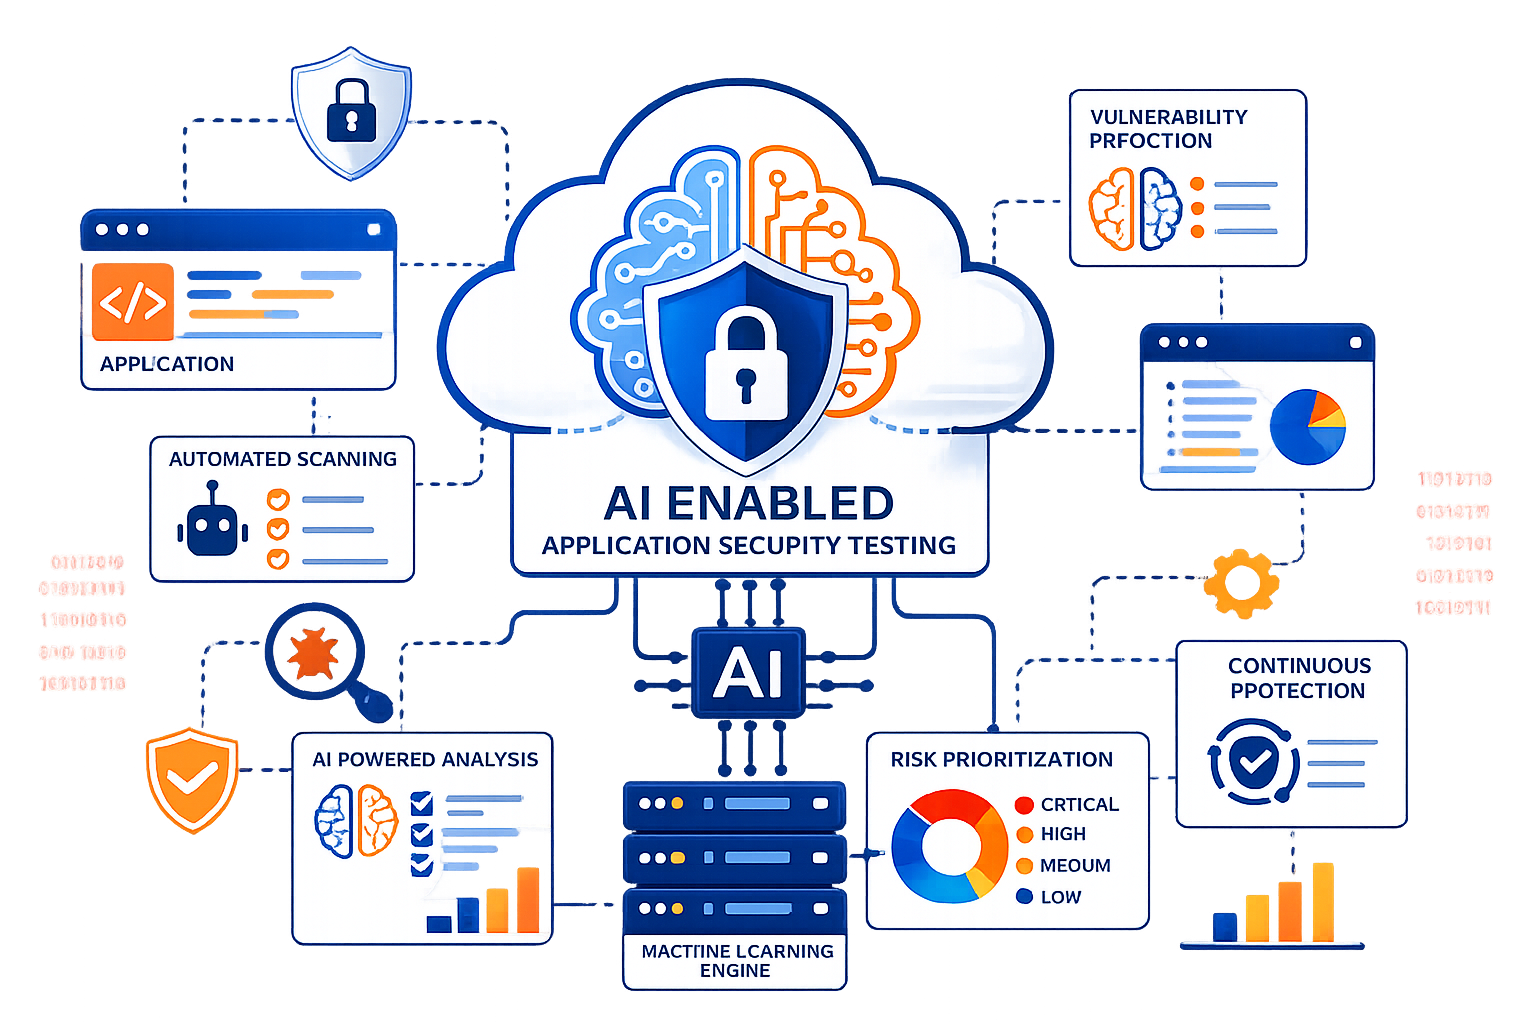
AI-Enabled Application Security Testing is a specialist assessment designed for applications that integrate large language models, generative AI, autonomous agents, or retrieval-augmented generation (RAG) pipelines — attack surfaces that traditional application pentesting frameworks were never built to cover.
Our AI security engineers manually probe every layer of your AI stack: system prompts, model APIs, tool-calling chains, vector databases, embeddings pipelines, and agent orchestration logic — uncovering prompt injection, data exfiltration, model inversion, and trust boundary failures that automated scanners cannot detect.
-
LLM-Native Threat Modelling We map every adversarial path specific to your AI architecture — from jailbreaks to indirect prompt injection — before your users discover them.
-
Regulatory & AI Act Readiness Align with EU AI Act, NIST AI RMF, and emerging AI security standards — with documented evidence of adversarial robustness validation.
-
Data Leakage & PII Protection Identify training data extraction, system prompt leakage, and cross-user context contamination vectors before they expose sensitive customer data.
-
Zero Disruption to AI Services All adversarial testing conducted safely against your AI stack with no model poisoning, no production data corruption, and no service interruption.
Based on aggregated AI application assessment data · 2023–2025
Our AI Application Security Testing Methodology
A rigorous, six-phase process aligned to OWASP LLM Top 10, NIST AI RMF, and MITRE ATLAS — delivering thorough, defensible results across every AI component in your stack.
Enumerate all AI components: LLM endpoints, agent tools, RAG pipelines, vector stores, embedding models, and trust boundaries across the full AI application stack.
Model AI-specific threats: prompt injection vectors, context window abuse, tool misuse paths, data flow across model boundaries, and adversarial input surface mapping.
Manual adversarial testing of LLM behaviour — jailbreaks, prompt leakage, guardrail bypass, data extraction, role confusion, and hallucination exploitation.
Controlled exploitation of AI agent pipelines — indirect prompt injection via tools, function call abuse, privilege escalation, and autonomous action chain subversion.
Poisoning attacks on vector databases, groundedness bypass, embedding inversion, cross-user context leakage, and retrieval manipulation to corrupt AI outputs.
Executive summary, full technical report with CVSS v3.1 and OWASP LLM severity ratings, attack chain diagrams, guardrail recommendations, and prioritised remediation roadmap.
Every finding mapped to OWASP LLM Top 10 categories and rated with CVSS v3.1, with annotated attack chain diagrams for rapid remediation prioritisation.
After remediation, we re-probe all identified vulnerabilities at no additional cost and issue a formal VAPT Certificate upon successful closure.
Live access to findings, AI-specific remediation guidance, and historical reports through an encrypted client dashboard.
What We Test Across Your AI Stack
Full-spectrum coverage across LLM integrations, autonomous agent systems, and RAG data pipelines — assessed from every adversarial angle your users and attackers can reach.
LLM Integration Testing
Targets the core language model integration: prompt injection, system prompt extraction, jailbreaking, safety guardrail bypass, insecure output handling, and model denial-of-service. We test all input/output channels your application exposes to end users or internal systems.
AI Agent & Tool Security
Tests autonomous AI agents that use tools, call APIs, browse the web, or execute code. We probe indirect prompt injection via tool outputs, privilege escalation through function calls, unintended autonomous actions, and trust boundary failures in multi-agent architectures.
RAG & Data Pipeline Testing
Assesses retrieval-augmented generation pipelines: vector database poisoning, adversarial document injection, groundedness bypass, embedding inversion, cross-user context leakage, and manipulation of the retrieval ranking that shapes model responses.
Choose Your AI Security Assessment Approach
Three adversarial engagement models — aligned to your level of internal AI documentation and the realism of the threat scenario you need to simulate.
- Simulates an external attacker or malicious end user
- Blind prompt injection and jailbreak discovery
- API fuzzing and output analysis for leakage
- Realistic threat: public-facing AI chatbots & copilots
- Simulates a privileged insider or leaked prompt scenario
- Targeted injection against known prompt structure
- Agent tool enumeration with partial permission context
- Realistic threat: SaaS AI features & internal copilots
- Deepest coverage across the entire AI architecture
- RAG pipeline, embedding and retrieval logic audit
- Code review of agent orchestration & tool definitions
- Realistic threat: pre-launch hardening & compliance
Every AI Attack Surface, Tested
Our assessments span the full OWASP LLM Top 10 and MITRE ATLAS threat catalogue — covering every known AI-specific attack class.
The Highest Standard of AI Security Testing
We don't just meet industry benchmarks — we help define them. Every AI security engagement is conducted by specialists who build and break AI systems daily.
OWASP LLM & MITRE ATLAS Aligned
Fully aligned to the OWASP LLM Top 10 and MITRE ATLAS adversarial ML threat matrix — every finding mapped, classified, and cross-referenced for audit-ready documentation.
Meticulous AI-Specific Reporting
Every finding documented with attack chain diagrams, adversarial prompt reproductions, impact evidence, CVSS v3.1 scoring, and prioritised guardrail recommendations — never a generic checklist.
AI Red Team Specialists
Every engineer on your engagement specialises in AI security: ML engineering backgrounds combined with offensive security expertise. No generalists — only practitioners who understand both disciplines.
Free Retest & AI Security Certificate
We verify every remediation at no additional cost. Upon successful closure, we issue an AI Security VAPT Certificate — a trusted credential for clients, auditors, and AI governance stakeholders.
Frequently Asked Questions
Everything you need to know about our AI-Enabled Application Security Testing service.
Our Partner's
GET STARTED
Fast-track Penetration testing
Start testing in 24 hours. Connect directly with our security experts. And centralize your testing with InfoSec Brigade
Connect With Us